Configure complete metadata indexing loops inside your global-vs-individual-schema-circuit blueprint to align structural site layers with real-time GraphRAG cross-encoders. By hardcoding automated schema blocks across two distinct infrastructure tiers, your system satisfies engine query parameters, merging main domain settings with granular post-level definitions.
1. The Global Schema Header Injection
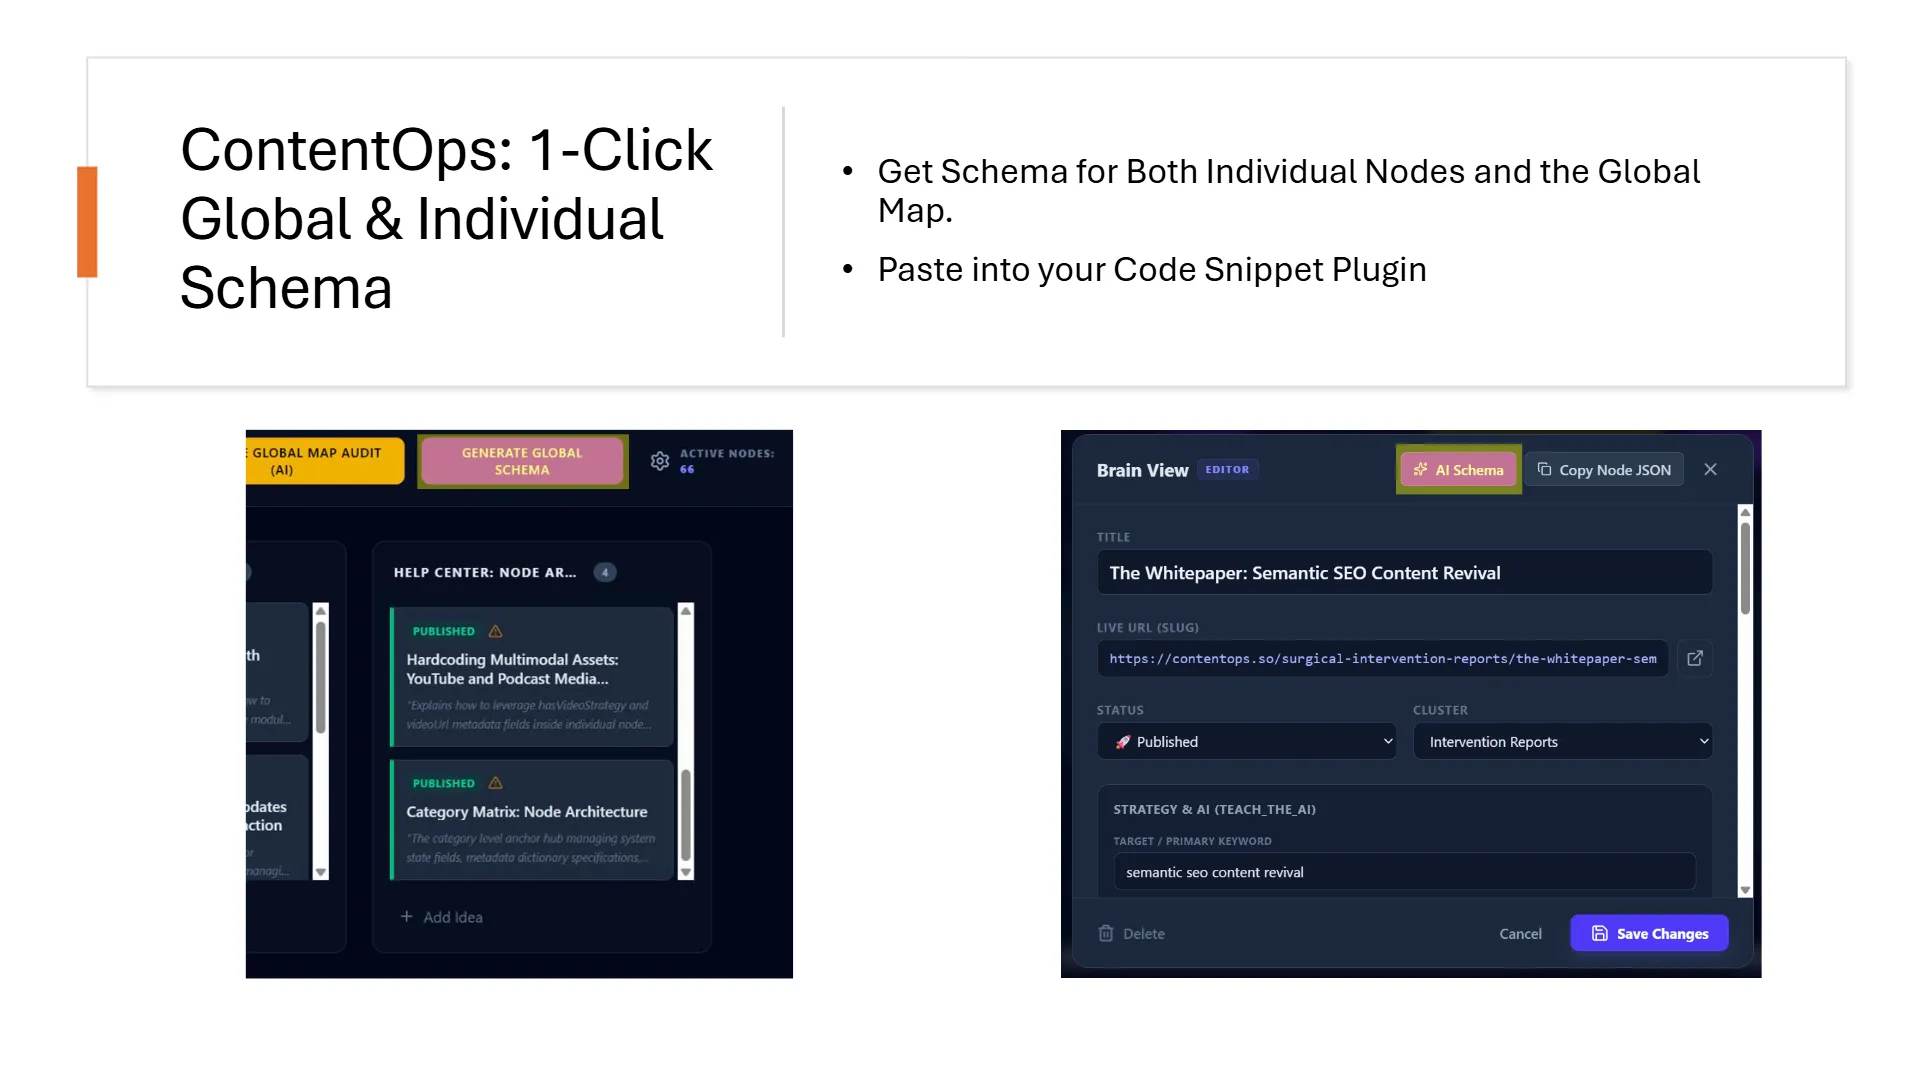
The first tier of the indexing circuit runs globally inside your website’s main container template header block. Clicking ‘Generate Global Schema’ commands the data pipeline to serialize your entire corporate footprint into a singular, cohesive DefinedTermSet schema container script. This file records the overarching brand identity, parent cluster names, and macro-relational edges of your network topology, presenting automated bots with a pre-computed architectural directory before they parse a single line of human prose.
2. The Individual Post Schema Sidecar
The second tier of the circuit lives localized directly within individual post text variables. Generated from the node metadata modal, this block is an explicit, compact Article data snippet that bypasses JavaScript execution scripts entirely. It maps the individual headline, body text vectors, and isolates 3 to 5 targeted entity variables under the about parameter array, explicitly anchoring the individual post as a nested element that isPartOf your main global knowledge graph ID. Together, these two tiers fuse your archive into an interconnected superhighway, preventing token dilution across complex B2B sectors.